View detailsOpen project ↗
PUBLIC SOFTWARE / HANGRY LABS
Tools built to runclose to home.
Open software for voice, speech, and local AI operations—packaged for real hardware, honest about trade-offs, and ready to explore.
06open projects
Locallocal first
Opensource available
PROJECT GALLERY
Pick a tool. See what it does.
Choose a card to unfold its details, or jump straight to the project.
Fast local speech
Voice previewHeart
af_heart0:00 / 0:00
KokoroTTS
A compact 82M-parameter TTS engine with 54 voices, nine language prefixes, a browser UI, and a practical HTTP API.
Best forFast narration, long-form generation, first-time local TTS users, and lightweight integrations.
Runs onRuns on CPU; NVIDIA GPU acceleration is optional.
82M parametersCPU friendly54 voicesUI + API
Stable multilingual TTS
02 / 06MeloTTS
A dependable multilingual speech engine packaged with full and English-focused images, UI, API, and sentence streaming.
Best forEnglish, Spanish, French, Chinese, Japanese, or Korean speech with predictable controls and integration routes.
Runs onCPU and NVIDIA GPU modes are supported.
6 language familiesStreamingUI + APICPU fallback
Massively multilingual voice lab
03 / 06OmniVoiceTTS
A broad TTS system for 600+ languages with voice design, reference cloning, reusable profiles, and OpenAI-compatible speech routes.
Best forMultilingual products, expressive voice design, consented voice cloning, and OpenAI-compatible local speech.
Runs onGPU recommended; CPU fallback needs roughly 2–7 GB RAM depending on cloning and ASR use.
6 GB minimum600+ languagesVoice cloningOpenAI-compatible API
Creative and true-to-life speech
04 / 06VoxCPMTTS
VoxCPM2 packaged for local generation, natural voice design, reference cloning, and transcript-guided cloning.
Best forCreative voices, realistic consented cloning, multilingual output, and advanced local speech experiments.
Runs onA large model: CPU fallback exists; a capable NVIDIA GPU is the practical path.
~8 GB VRAMVoice designVoice cloningUI + API
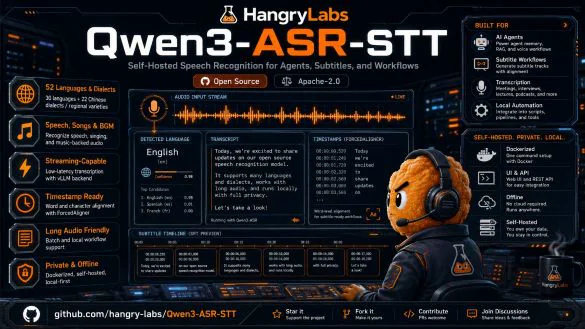
Speech to text
05 / 06Qwen3-ASR-STT
A local ASR service for multilingual transcription, language detection, timestamps, microphone streaming, and OpenAI-compatible clients.
Best forTranscription, captions, meeting audio, voice interfaces, and applications already using OpenAI-shaped APIs.
Runs onNVIDIA GPU workflow; the default 0.6B model is the lighter starting point and the 1.7B model trades memory for capability.
4.62–6.89 GiB measuredMultilingual ASRRealtime sessionsOpenAI-compatible API
llama.cpp operations
06 / 06llama.nodrama
A focused diagnostics interface for llama.cpp slots, KV cache behavior, and the operational details hidden behind a local LLM endpoint.
Best forUnderstanding a running llama.cpp server, diagnosing capacity, and keeping local inference boring in the best way.
Runs onHardware-neutral companion UI; requirements are determined by the llama.cpp server it observes.
Slot diagnosticsKV cache insightLocal endpointNo-drama operations