Docker Desktop or Docker Engine. An NVIDIA GPU is optional; CPU mode works too. The full image includes English, French, Chinese, and Japanese model families. Spanish and Korean are optional online installs that require reviewing their upstream terms.
Multilingual speech studio Stable v1.0.1 or rolling latest
MeloTTS
Multilingual speech, shaped and streamed on your own machine.
A local TTS workspace with eight models across six languages, a responsive browser UI, OpenAI-compatible and native APIs, six output formats, and sentence-streamed MP3/PCM.
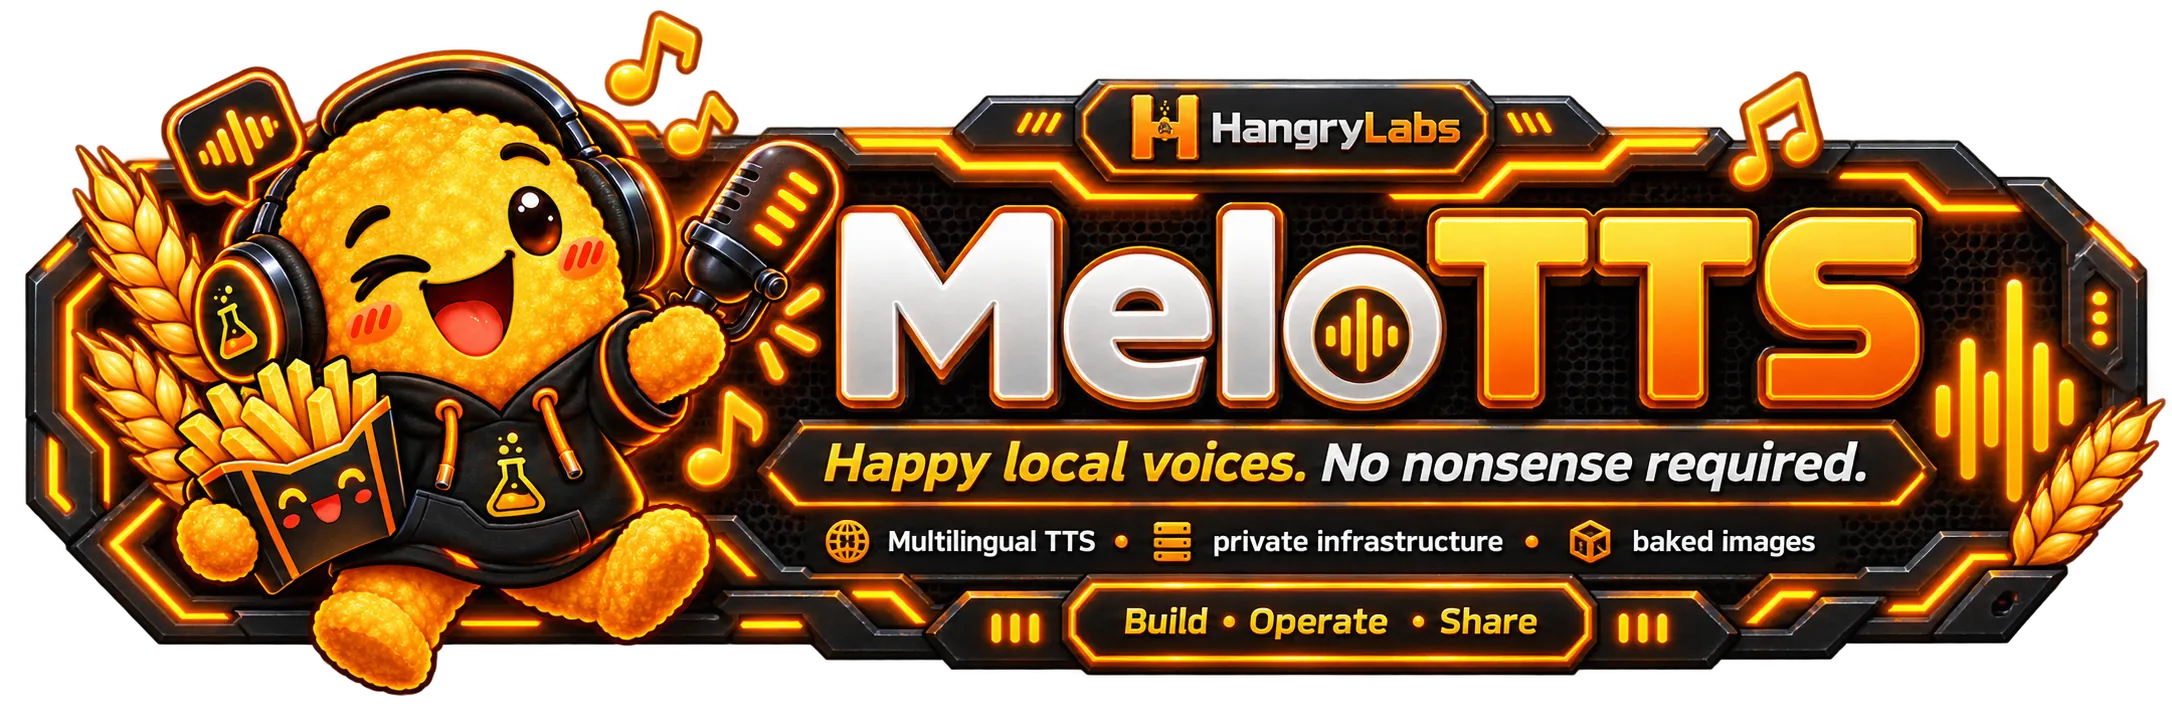
Open Generate, choose a loaded language model and voice, adjust the synthesis or output controls, and select Generate. Stream, API, and System provide sentence streaming, integration details, model management, and GPU telemetry.
Baked core models work offline after the image is pulled, and text and generated audio stay local. MeloTTS is AGPL-3.0: modified distributions and modified network services must offer their corresponding source to users.
What is included
A complete local workspace, not just a model.
- Eight models across six supported languages
- Generate, Stream, API, and System workspaces
- OpenAI-compatible and native APIs with optional bearer auth
- MP3 and PCM sentence streaming plus six OpenAI output formats
- Hardened experimental SSML for multi-voice dialogue
- Waveform trimming, model residency controls, and GPU telemetry
The actual application
A complete multilingual speech workspace.
Generate and Stream expose native synthesis and output controls without hiding the selected model. API documents local integrations, while System manages optional language packs, loaded models, runtime state, and GPU telemetry.