Docker and a supported NVIDIA GPU on Windows or Linux. The measured Nano baseline peaked at 8,491 MiB of VRAM on RTX 5070 Ti; 12 GB is the conservative tier. Run one model-serving container per GPU.
Creative and true-to-life speech Stable v1.0 or rolling latest
VoxCPMTTS
Design, clone, and stream voices in 30 languages on your own GPU.
A local VoxCPM2 workspace for 30-language generation, voice design, reference and transcript-guided cloning, reusable profiles, progressive MP3 streaming, and HTTP APIs.
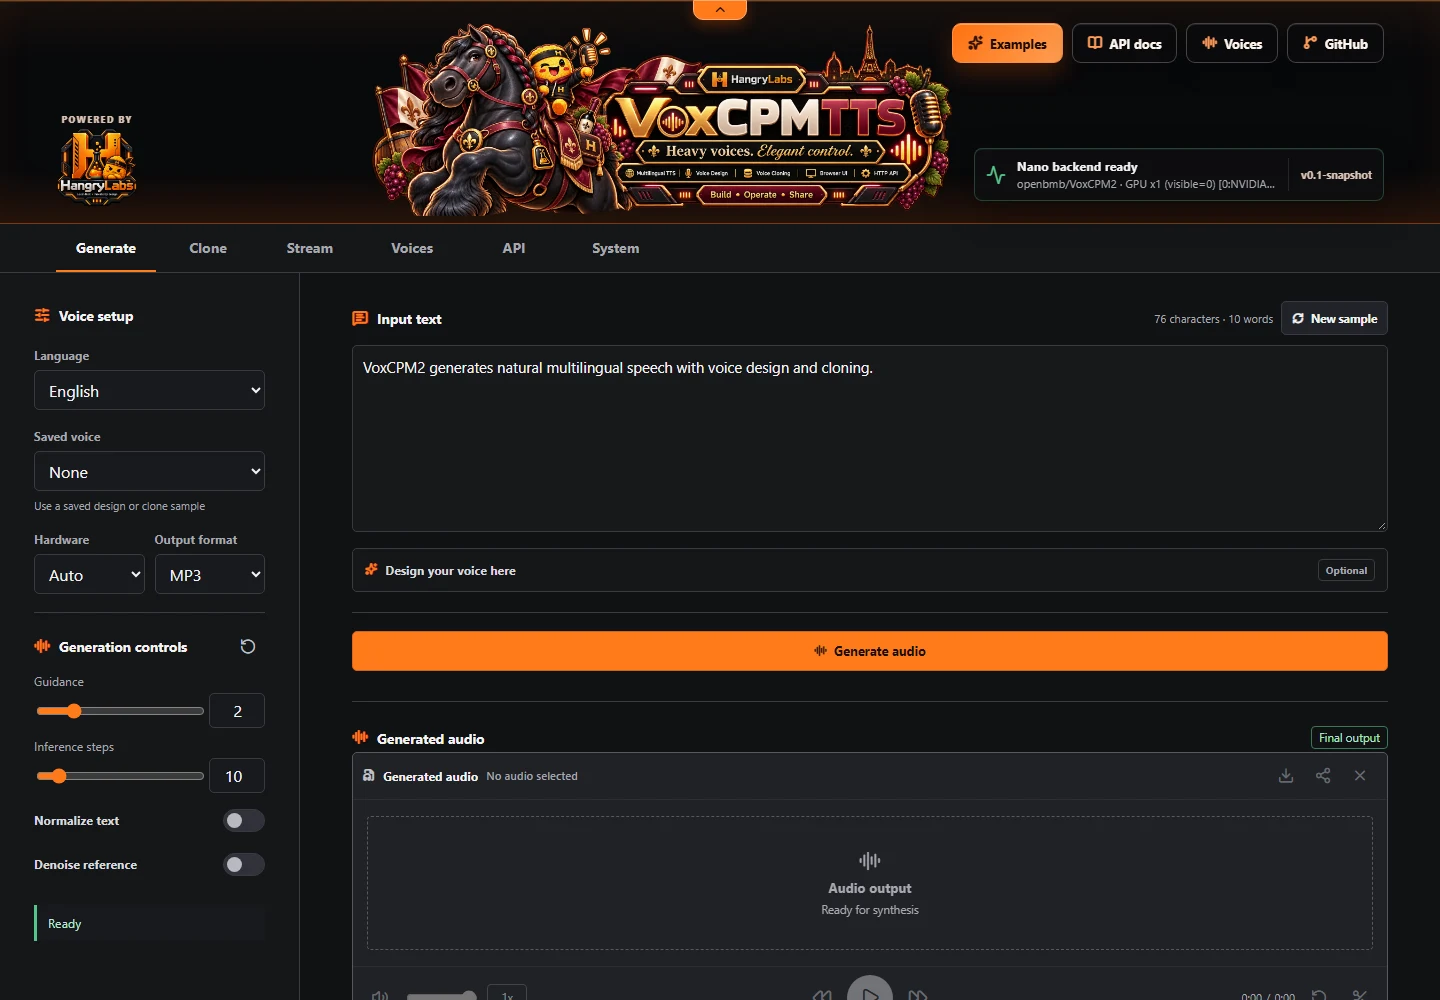
Open Generate for natural speech or voice design, or Clone to upload or record a consented reference. Stream provides progressive playback, Voices stores reusable profiles, and API and System expose integration and runtime details.
Text, reference audio, saved profiles, and generated speech stay on the machine running the container. Clone only voices you have the rights and consent to use; never use it for impersonation, fraud, harassment, or deception. Docker image components retain their own license terms.
What is included
A complete local workspace, not just a model.
- VoxCPM2 generation across 30 languages
- Voice design, reference cloning, and transcript-guided cloning
- Persistent reusable voice profiles
- Progressive MP3 streaming plus WAV, MP3, FLAC, and OGG
- Generate, Clone, Stream, Voices, API, and System views
- Nano-vLLM CUDA graphs with a measured 0.271 median RTF
The actual application
Six focused workspaces for expressive local speech.
Generate handles natural speech and optional voice design. Clone accepts recorded or uploaded references, Stream plays progressive output, Voices preserves reusable profiles, and API and System expose the service and GPU runtime.