Docker on Linux x86-64 or compatible Docker Desktop. CPU mode works; NVIDIA acceleration needs a CUDA 13-compatible driver. Full images include verified weights; tiny downloads them on first use.
Voice restoration studio Stable v1.0.1 or rolling latest
Sidon
Restore speech. Separate voices. Keep your audio local.
Restore single-speaker audio, split a two-speaker mixture, enhance both tracks, or convert formats without loading a model, using one local studio and audio-job APIs.
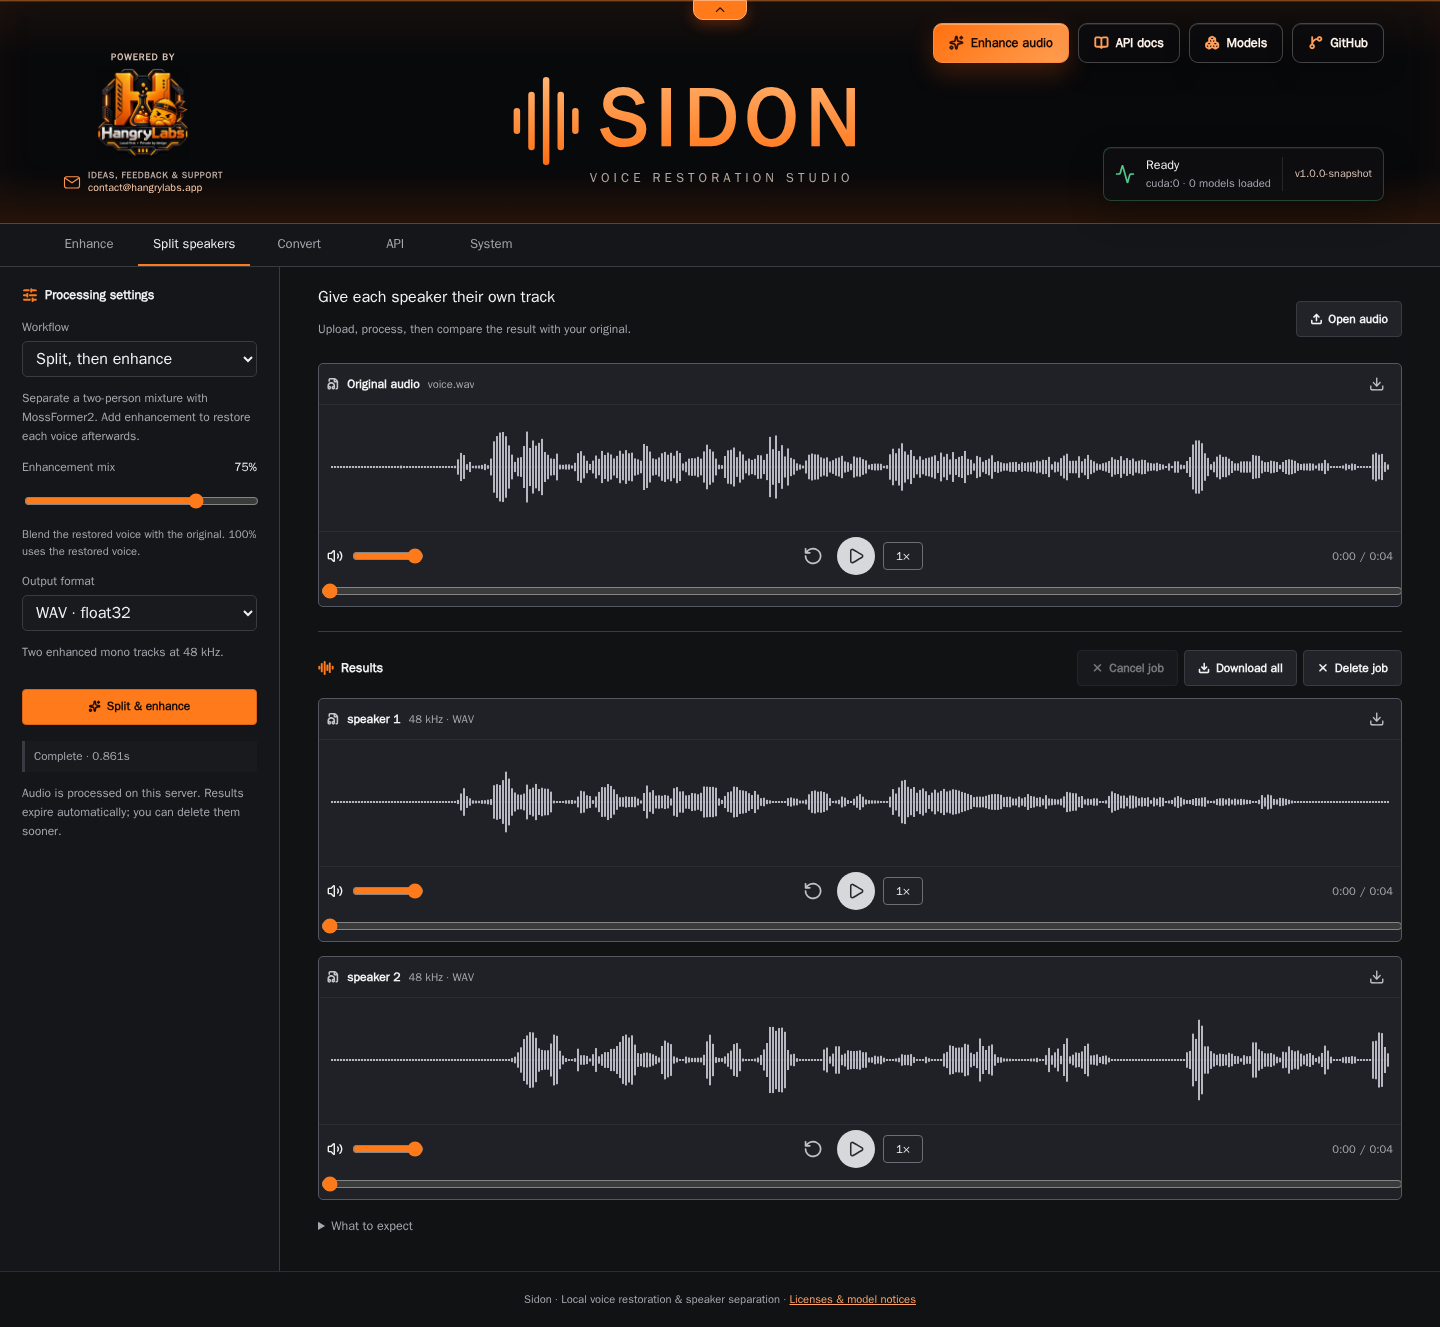
Upload a recording, select Enhance, Split speakers, Split then enhance, or Convert only, and process. Compare original and output before downloading individual files or a ZIP.
Processing and retained jobs stay on your server until deletion or expiry. Restoration can change timbre or introduce artifacts; it cannot reliably recover missing words. Model and runtime licenses remain separate.
What is included
A complete local workspace, not just a model.
- Single-speaker restoration to mono 48 kHz
- Two-speaker separation to mono 16 kHz tracks
- Separate then restore both tracks at 48 kHz
- Model-free conversion with channel preservation
- WAV, FLAC, Opus, MP3, AAC/M4A, and Vorbis exports
- Native audio APIs, FIFO jobs, cancellation, and GPU controls
The actual application
Compare the original and restored recordings.
The studio combines upload, workflow selection, original/result waveform players, and downloads. System manages model residency, retained jobs, settings, and GPU charts; the API supports direct and queued audio responses.