Docker Desktop or Docker Engine. An NVIDIA GPU is recommended; CPU fallback needs about 2–7 GB RAM depending on cloning and ASR. The default checkpoint is CC-BY-NC and is not licensed for commercial use; bundled tokenizer assets have separate terms.
600+ language voice studio Stable v1.0 or rolling latest
OmniVoiceTTS
Design, clone, and direct voices across more than 600 languages.
A local voice studio for 600+ languages with voice design, microphone and reference cloning, reusable profiles, SSML-H dialogue, streaming, and OpenAI-compatible APIs.
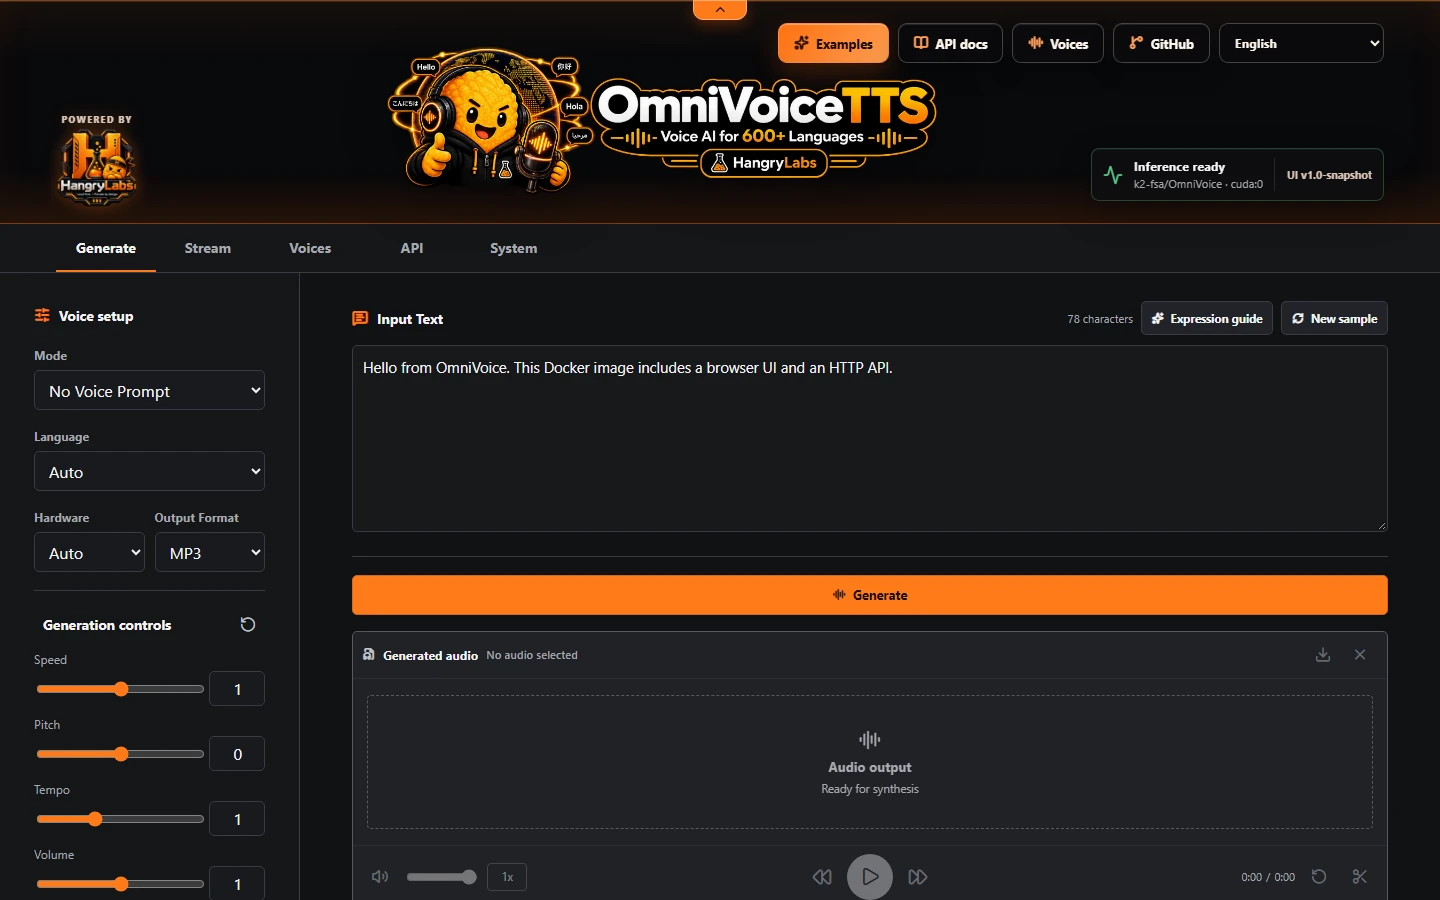
Open Generate, choose Text, SSML, or SSML-H, select automatic voice, voice design, or a saved/reference clone, and generate. Stream, Voices, API, and System provide the wider workflow.
The full image includes pinned model assets for offline-friendly use after download. Text, references, profiles, and generated audio stay local. MCP is disabled by default and should only be enabled for trusted clients.
What is included
A complete local workspace, not just a model.
- 600+ speech languages and 60 interface languages
- Automatic voice, voice design, and microphone/reference cloning
- Reusable saved voice profiles
- Plain text, SSML, and SSML-H dialogue
- Native and OpenAI-compatible APIs with streaming
- Opt-in compact and advanced MCP endpoints
The actual application
Five focused workspaces, one local service.
Generate and Stream keep synthesis controls close to the text. Voices manages reusable profiles, API exposes local integration details, and System brings runtime, memory, GPU, and MCP controls together.